- Self-hosted DeepSeek R1 and Qwen 2.5 cut enterprise token expenditure by up to 85% compared to proprietary commercial APIs.
- Open weights allow complete data isolation within private VPCs, guaranteeing zero IP leakage.
- Optimized inference engines (vLLM, TensorRT-LLM) deliver higher throughput for batch enterprise workloads.
1. The Explosive Rise of Open-Weight AI Models
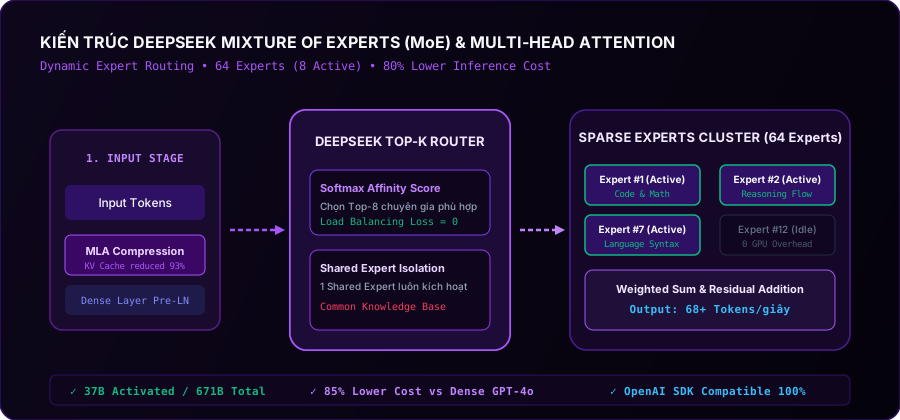
The launch of DeepSeek R1 and Qwen 2.5 has fundamentally disrupted the enterprise AI landscape. State-of-the-art open-weight models now match or exceed proprietary models (GPT-4o, Claude 3.5 Sonnet) across STEM reasoning, code generation, and factual synthesis.
2. Architectural Strengths of DeepSeek R1 and Qwen 2.5
- DeepSeek R1: Engineered with large-scale Reinforcement Learning without prior supervised fine-tuning, delivering mathematical and algorithmic reasoning comparable to OpenAI o1 at a fraction of the inference cost.
- Qwen 2.5: Optimized for ultra-dense multilingual comprehension and long-context retrieval, providing superior support for Asian enterprise document pipelines.
3. Comprehensive Cost & Throughput Benchmark Table
4. Sovereign AI: Eliminating Data Leakage via Private Deployments
For legal, healthcare, and financial enterprises, sending proprietary contracts and customer records to commercial third-party APIs presents unacceptable compliance and trade secret risks.
F2C Labs specializes in architecting Private Sovereign AI Infrastructure—deploying quantized open models on dedicated enterprise clusters with private vector search (pgvector) and local embeddings, guaranteeing 100% data containment.
5. Enterprise Adoption Strategy: When to Self-Host vs Use APIs
- Use Cloud APIs: During early prototyping, non-confidential exploratory research, or low-frequency batch operations (< 100k tokens/day).
- Deploy Sovereign Infrastructure: When processing sensitive enterprise IP, customer PII, or high-volume automated workflows exceeding millions of tokens daily.
- [1] DeepSeek-R1: Incentivizing Reasoning Capability in LLMs via Reinforcement Learningarxiv.org
- [2] Qwen2.5 Technical Report: Open Foundation & Instruction Modelsarxiv.org
- [3] OpenAI API Pricing & Token Consumption Specificationsopenai.com
Founder & CEO
Software engineer specializing in AI-integrated product development on Google Cloud Platform (GCP). Leads overall product lifecycle from distributed backend architecture to production deployments, accelerating business go-to-market.